Push-button deployment.
Set up your model and target, then launch one automated workflow from compilation through to inference on supported hardware.
INTRODUCING VERTIS
From your AI model to a running FPGA.
Vertis automates compilation, verification, programming and inference in one push-button workflow for supported models and targets.
FOR AI & EMBEDDED ENGINEERING TEAMS
01 / MEET VERTIS
Between a model and working hardware sits a complex chain of engineering decisions. Vertis turns the supported deployment path into a push-button workflow.
Import your ONNX model, define the target and constraints, then start deployment. Vertis handles the supported workflow through compilation, verification, FPGA programming and inference.
Vertis is built by AI and FPGA engineers who have experienced the challenges of deploying AI on FPGAs firsthand. We built it to simplify the workflow we needed ourselves.
Set up your model and target, then launch one automated workflow from compilation through to inference on supported hardware.
A target-neutral compiler with separate vendor backends, designed to connect with different FPGA toolchains.
Keep model identity, build settings, generated artefacts and verification outcomes together.
02 / THE WORKFLOW
One push-button workflow. Four connected stages.
Explore what Vertis automates for supported deployments.
Bring an ONNX inference model. Vertis inspects its graph, inputs and operators, then connects it to the intended hardware target and deployment settings.
Working on real hardware. The supported automated workflow has been demonstrated with multiple AI models.
See current scope03 / VENDOR-AGNOSTIC ARCHITECTURE
Vertis is vendor agnostic by design. A common compiler connects to separate vendor backends, keeping your deployment workflow consistent across FPGA toolchains.
Each backend handles its vendor’s synthesis, implementation and programming tools. Vertis brings them into one push-button deployment path.
Apply with your targetVENDOR-AGNOSTIC COMPILERENGINEERING YOU CAN INSPECT
A deployment is more than a generated file. Vertis records the context behind each build, so engineers can inspect the artefacts and the checks that produced them.
04 / BUILT FOR THE EDGE
For teams developing AI within real power, compute and connectivity constraints.
Explore onboard inference for applications where downlink, power and compute are limited.
Connect the model to a hardware deployment path shaped around the application’s constraints.
Develop onboard intelligence for systems operating beyond dependable remote connectivity.
05 / THE ENGINEERING BEHIND VERTIS
Setanta brings together spacecraft AI, FPGA systems and embedded engineering. Alongside Vertis, our work spans onboard intelligence and modular computing for the mission.
Explore the applications we work on and the hardware we build around them.
Built in Dublin. Designed for the edge.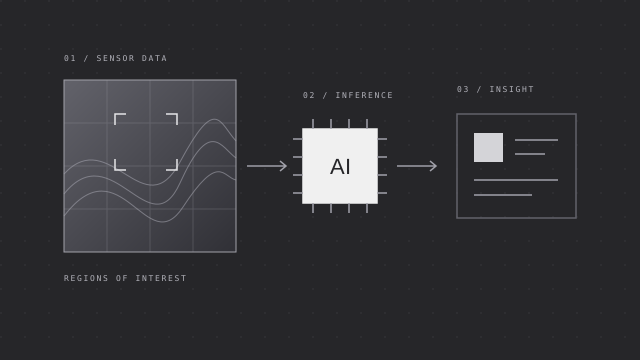 CONCEPT / ONBOARD INFERENCE
AI & ONBOARD INTELLIGENCE
From Earth observation to navigation and sensor alerts. Shape AI workloads around the decisions your system needs to make.
Explore AI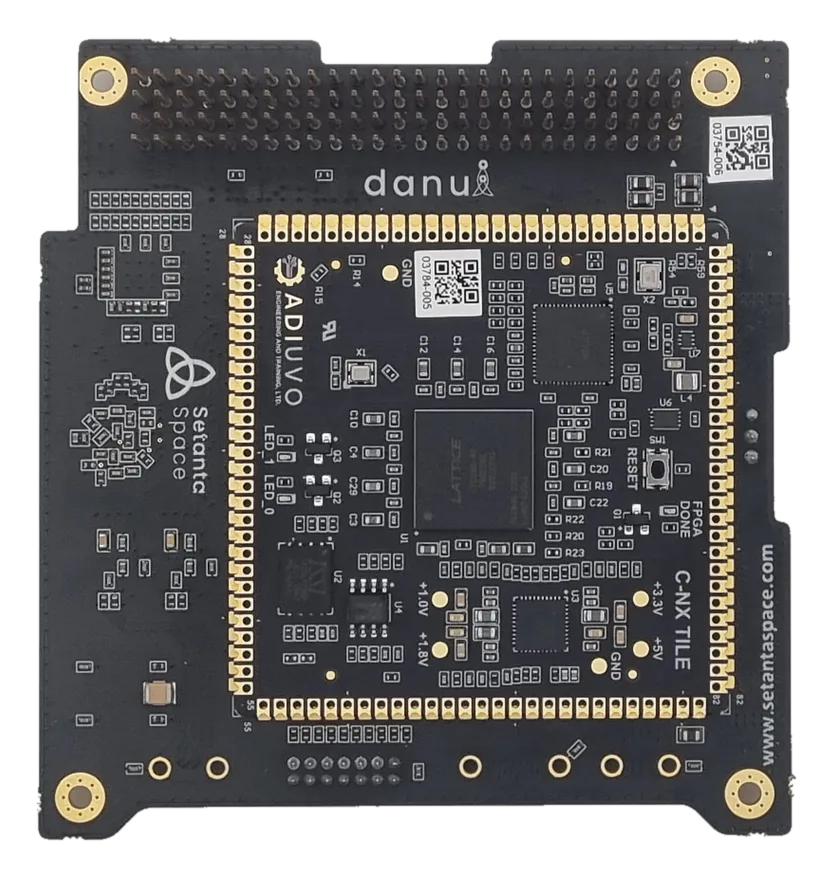 DANU / MODULAR ONBOARD COMPUTE
ONBOARD COMPUTERS & SPACE TILES
A modular hardware range for spacecraft computing, with FPGA, processing and memory options for mission-specific capability.
Explore hardwareA CLEAR VIEW OF THE PRODUCT
Vertis is under active development.
Let’s define an evaluation around your model and hardware.
The supported automated workflow - model import, compilation, FPGA programming and inference - has been demonstrated using multiple off-the-shelf AI models on AMD FPGA hardware.
Vertis has a vendor-independent integration architecture. This does not mean every device, model or toolchain version is validated. Additional backends and target validation are being developed; we assess your intended configuration with you.
Yes: ONNX is the canonical model format. Support depends on the graph, operators, shapes, numerical representation and target. We can discuss a bounded evaluation of your inference model and the criteria that matter to your team.
THE VERTIS CLOSED ALPHA
Help shape push-button AI deployment.
Tell us what you’re building and where you want to run it.
Your model. Your hardware.
Our next conversation.
We’re inviting engineering teams to apply for the Vertis closed alpha. We’ll review your application to understand your use case and fit with the supported workflow.